Before asking an engineering team to explain a low score, check whether the scorecard had enough evidence to assess its work. An overall result can look authoritative even when important parts of the picture are missing. If those gaps are counted as poor performance, the team ends up answering for the limits of the measurement.
A low result supported by good evidence can justify a closer look at how the team is working. Missing evidence calls for a different next step: understand the gap before drawing a conclusion about performance. That distinction should be visible before the score reaches a leadership meeting.
Start with what is actually known
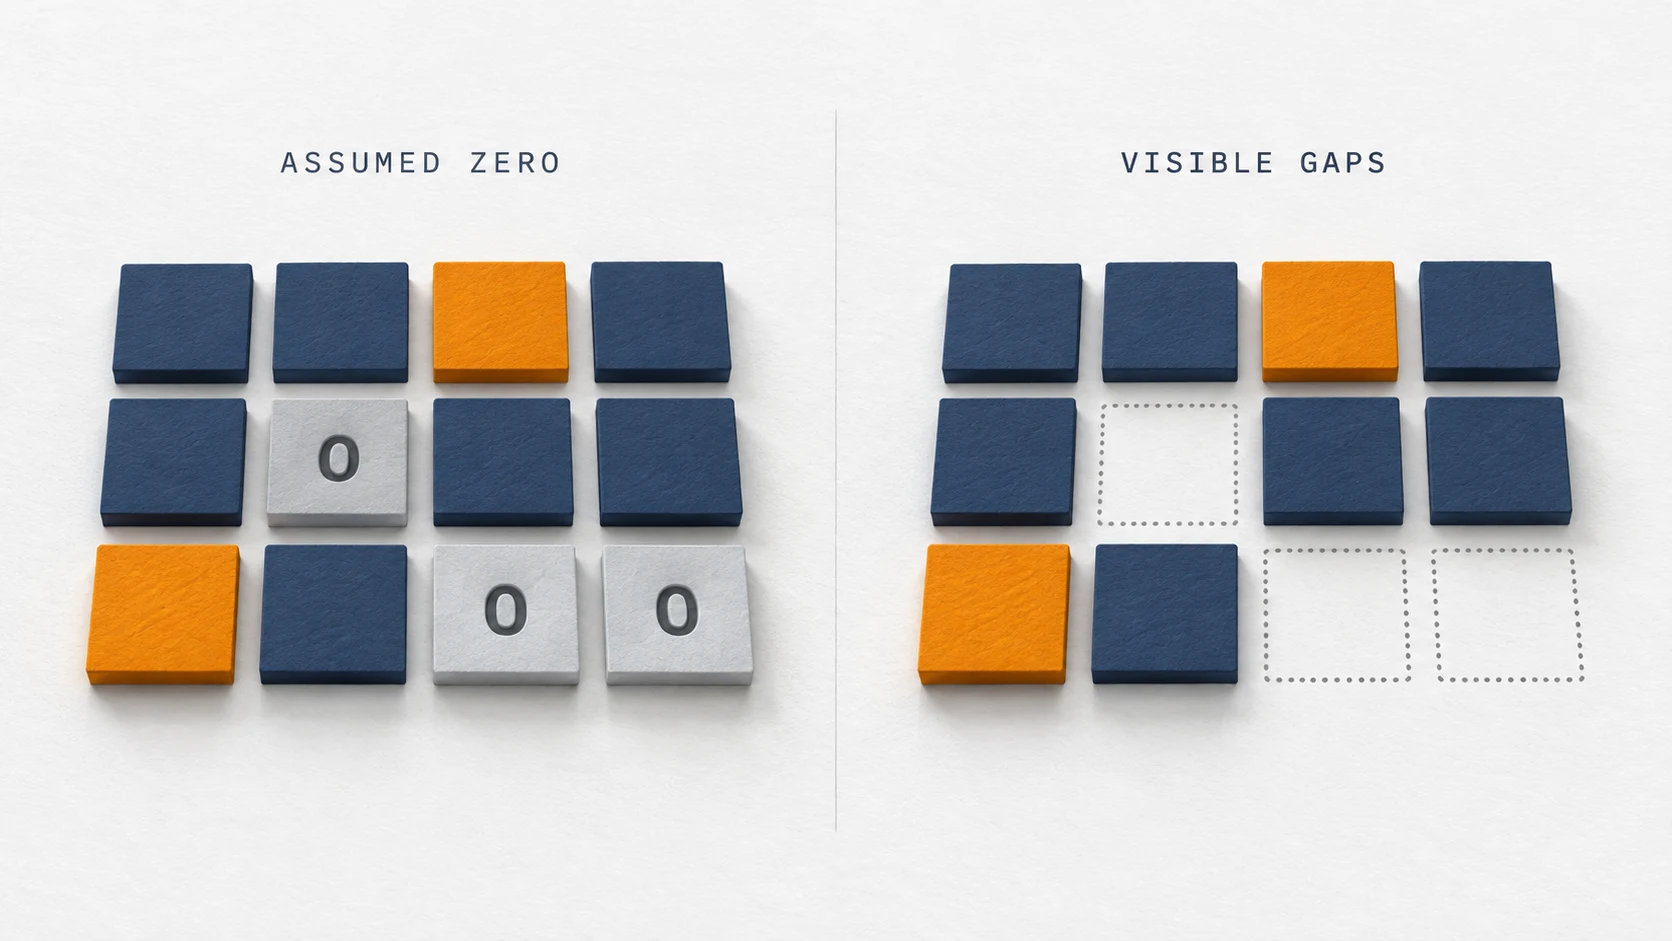
Consider a hypothetical team whose scorecard includes delivery, quality and incident recovery. There is useful evidence about delivery and quality, but no usable recovery data for the period. Perhaps the incident source has not been connected. Perhaps the team had no qualifying incidents. Those situations need different explanations, and neither gives us a measured recovery time.
If the scorecard inserts a zero for recovery, the team’s overall result falls because of something we could not assess. A leader might ask the team to improve its recovery process without first establishing that there is a problem with it. The dashboard has turned a gap in its own evidence into work for somebody else.
Leaving the unavailable dimension out avoids that particular mistake. But the remaining score still needs context. It describes the dimensions we could assess. If recovery evidence becomes available next month, the overall score may change partly because the assessment now covers more of the team’s work. Reading that movement as improvement or decline without checking the coverage would create another misleading conclusion.
Coverage belongs beside the result
A useful scorecard should make its limits easy to see. Coverage tells us which dimensions, teams and periods are represented. Confidence helps us judge how much weight to put on the assessment. The strength of the evidence should influence the strength of the conclusion.
That means making unavailable dimensions visible as unavailable, explaining why where possible, and showing enough context to understand what went into the overall result. The reader should not have to reconstruct the methodology to discover those limits.
It also means being careful with comparisons. Two teams can have the same overall result while having very different evidence behind it. One may have broad coverage across the assessment. Another may have a useful view of delivery and very little visibility elsewhere. A ranking hides that difference and encourages a level of certainty the evidence does not support.
Bring the score back to the team
When reviewing the result with the team, leave room for them to explain the work it represents.
Some useful questions are straightforward: Does this reflect the work you were trying to get done? What important work is missing? Has anything changed in how the data is captured? Is there enough evidence here to choose an improvement, or do we need to investigate first?
The answers can change the next step. A team may identify a genuine problem in how work moves through review, or explain that a major piece of work sits outside the connected sources. That context helps the leader work out whether there is an improvement to make, rather than getting stuck in an argument about whether the number feels fair.
There is still accountability in this approach. Where the evidence supports a concern, agree on the problem, choose an action and decide how to review the outcome. Where coverage is weak, decide whether closing the gap would improve an actual decision. Collecting more data has a cost, and a fuller dashboard is not automatically worth that cost.
Keep the purpose of the scorecard clear
This is part of the thinking behind Simyl Flow. Dimensions with absent or zero-confidence data are excluded from the organization-level effectiveness calculation, rather than being counted as zero. The available dimensions contribute to the result. That prevents missing evidence from mechanically lowering an organization’s score, while leaving an important responsibility with anyone interpreting it: understand what the result represents.
The purpose is to help teams improve outcomes and help leaders have better coaching conversations. Activity can provide context, but a count of commits, tickets or comments cannot establish on its own whether a team achieved what mattered. Turning incomplete signals into a ranking of employees takes the assessment further than the evidence can support.
A useful scorecard should help the team agree on what to do next. When the evidence is incomplete, understanding the gap may be the right first step. Keeping that uncertainty visible makes it easier to act on the findings that are strong enough to support a decision.
Continue reading
- The Bottleneck Moved to Code Review. Your Metrics Didn't.Throughput is up and delivery is down, and the four keys will not tell you why. Under heavy AI adoption the constraint left the keyboard and settled in the review queue — median time in PR review up 441.5%, PRs merged with no review at all up 31.3%. Here is what to instrument instead. · 7 min read
- Measuring What AI Actually Does to Your TeamThe AI productivity narrative doesn't match the data. Here's how to understand AI's real impact on your specific team—without surveillance. · 10 min read
- Teaching Taste: The New Job of the Engineering ManagerAI ate code review and the apprenticeship that came with it. The engineering manager's job didn't disappear — it inverted. Coaching used to be the bonus skill. It's now the whole job, and the strong managers already sense it. · 11 min read